Case record / Education SaaS
Cohort Learning Platform Blueprint
A conceptual delivery blueprint pending verification of project provenance, permissions, implementation status, and outcomes.
Published outcome claim / not independently verified here
Conceptual reference only; no client result is claimed.
Request a similar build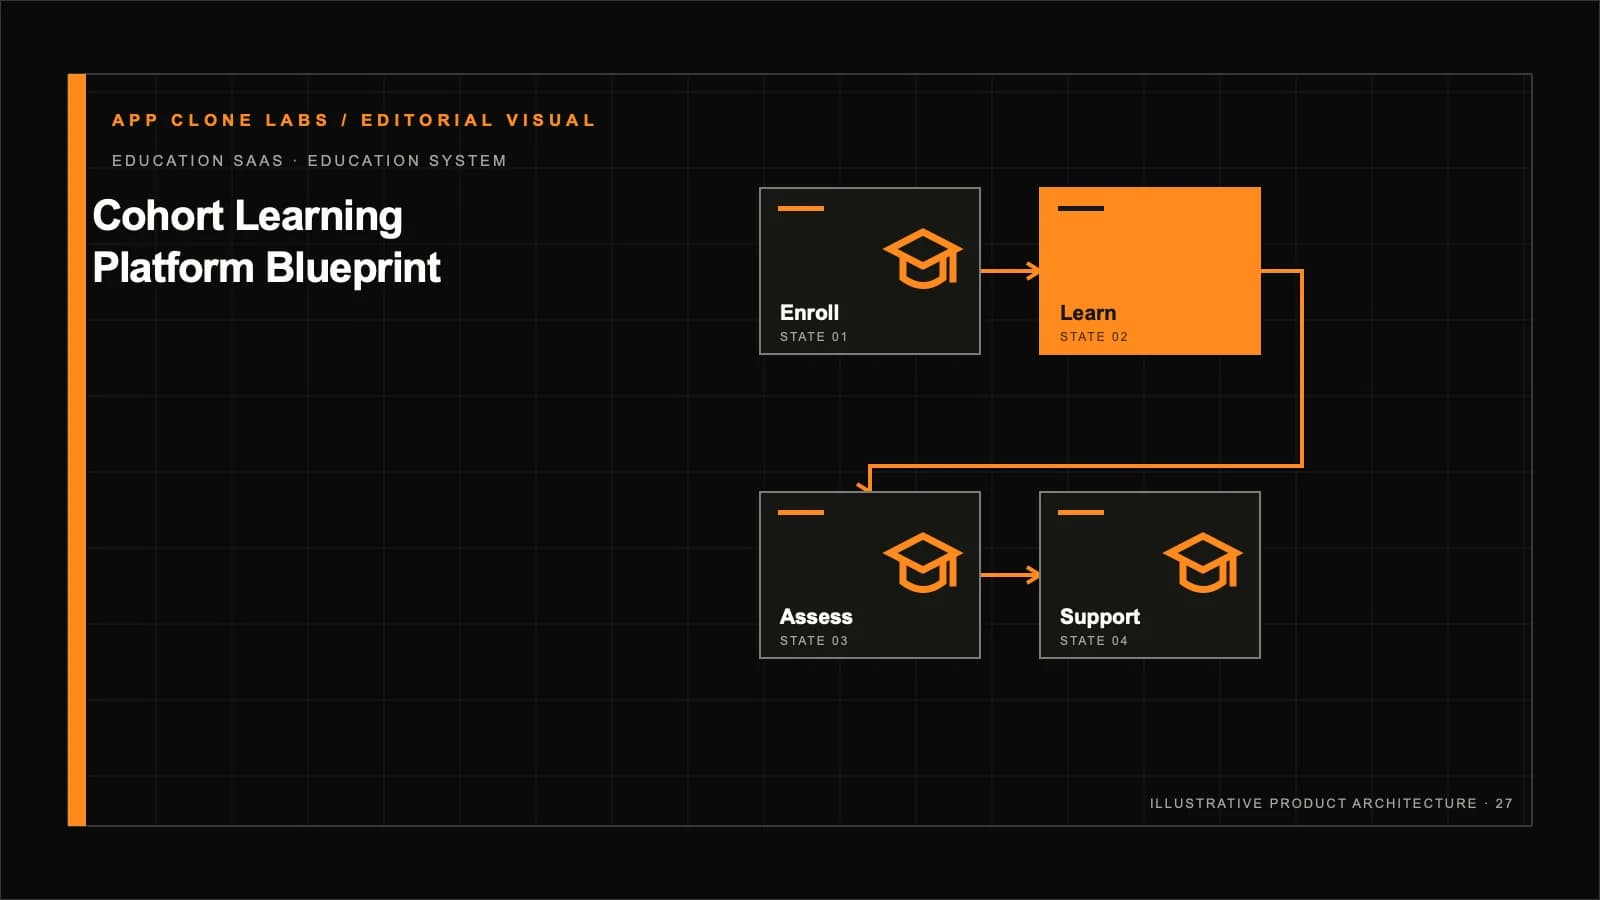
Proof status / evidence boundary
What this record can and cannot establish
Recorded project context
The industry, summary, service list, stack, narrative, and body are fields supplied by the case-study record.
Architecture and workflow
The workflow and technology labels describe the published delivery scope. They are not presented here as a new contractual commitment.
Outcome evidence boundary
Public outcome evidence is not attached to this record.
Evidence status: Blueprint / Last reviewed: Not recorded
Context / delivery read
A similar product needs workflow clarity before interface polish.
The fastest path is to map the commercial loop, user roles, admin controls, integrations, reporting, and launch handoff before design and engineering scale up.
Recorded services
Workflow and deliverables
Role-specific user journeys before interface design
Admin, support, reporting, and operations controls
Payment, notification, map, media, or AI integrations scoped early
Launch documentation, cloud context, and ownership handoff
The education team wanted a cohort-based learning product with payments and progress tracking, but did not want to build a bloated LMS before proving course demand.
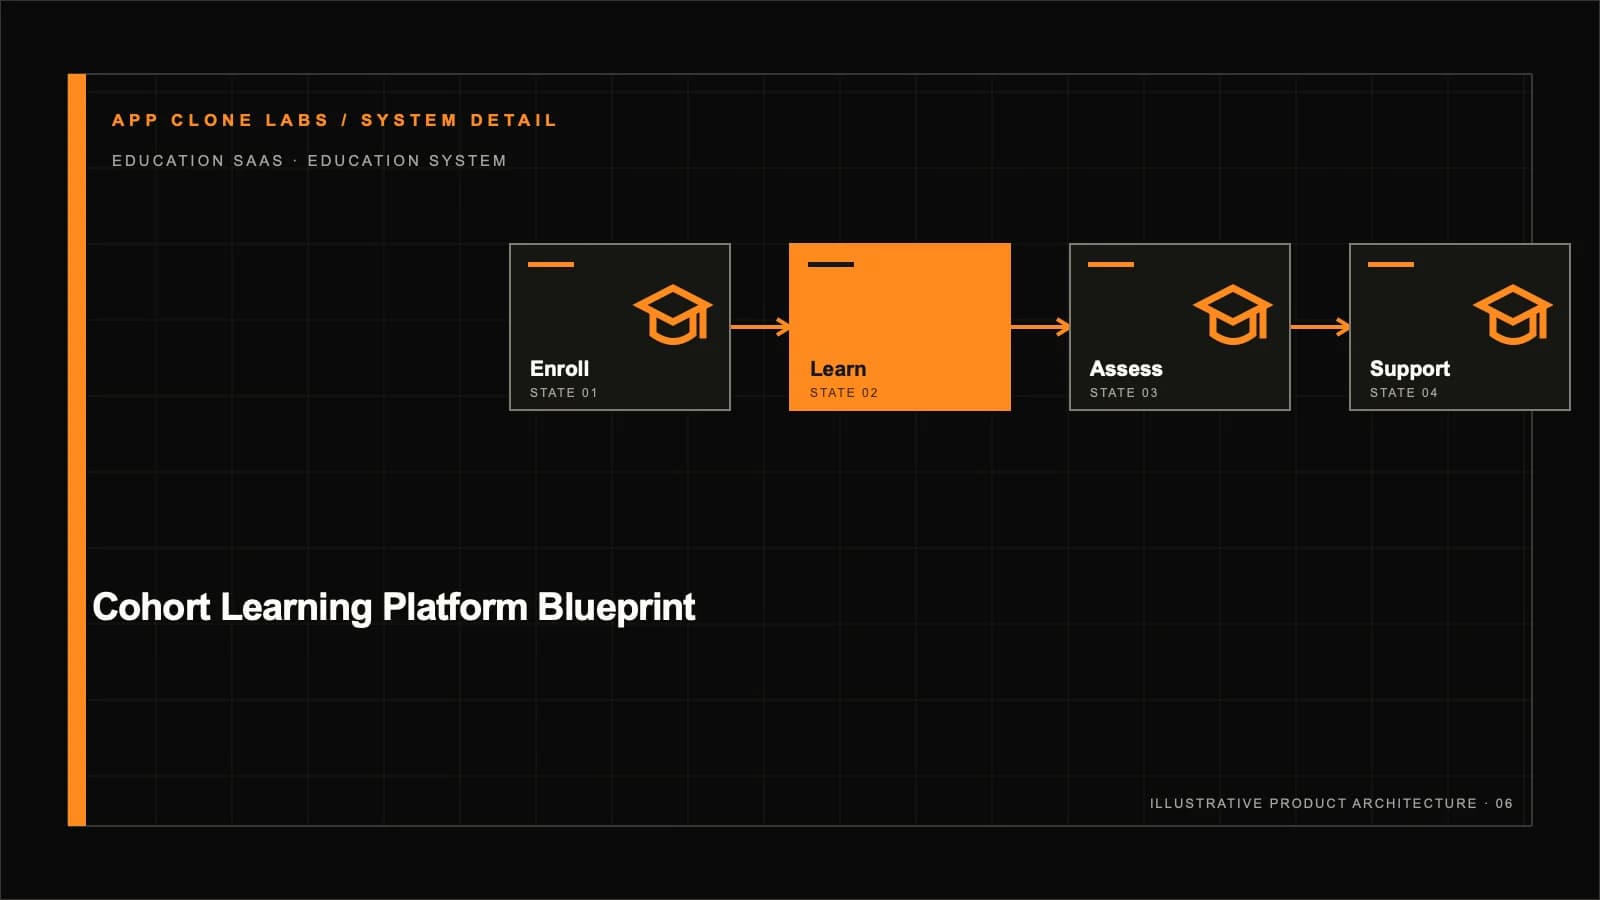
The first release was shaped around course catalog, cohort enrollment, lesson access, assignment submission, instructor review, learner progress, payment states, and support workflows.
The anonymized proof set included a learner journey, instructor workflow, course publishing checklist, analytics event map, and expansion roadmap for certificates, community, and enterprise licensing.
Technical architecture and system design
LearnLoop was architected as a Next.js learner and instructor application backed by a Node.js service layer and PostgreSQL on AWS, with Stripe handling cohort enrollment payments via webhooks and Sanity managing course content through a versioned content model. Cohort scheduling was modeled as a first-class entity linking courses, instructors, and enrolled learners, so progress tracking and assignment access could be scoped to a specific cohort rather than a generic course record, which prevented the common LMS bug where a learner enrolled in two cohorts saw progress bleed between them. Lesson access was governed by an enrollment-state machine—enrolled, active, completed, withdrawn, refunded—so every content gate could be evaluated deterministically and a withdrawn learner lost access immediately without a manual cleanup job. Assignment submission was stored as a versioned record so instructor review could compare iterations without losing prior feedback, and each version was immutable once written so a learner could not retroactively edit a submission after an instructor had graded it. The enrollment service also tracked a per-cohort capacity limit enforced at the database level so a race condition during a popular cohort launch could not oversell seats, with a waitlist mechanism that promoted the next learner automatically when a seat freed up through a withdrawal or refund.
API design separated the learner journey from the instructor management journey, with progress tracking and certificate eligibility computed server-side rather than trusted from the client, so a learner could not mark their own lessons complete by manipulating local state. Real-time requirements were modest, but assignment status updates used a lightweight event channel backed by a Postgres LISTEN/NOTIFY fan-out so learners and instructors saw consistent state without polling, with a fallback long-poll for browsers that dropped the notification socket. The architecture deferred community features, enterprise licensing, and advanced analytics to later phases so the first release could prove the cohort learning loop under real enrollment, and each deferred module was documented with the enrollment-volume trigger that would justify building it. Sanity was chosen for course content so instructional teams could publish lessons without engineering involvement, while transactional data stayed in PostgreSQL, and the two were joined at the API layer through a content reference ID so the transactional store never duplicated content that Sanity owned.
Development methodology and sprint breakdown
The build ran in two-week sprints, opening with a discovery sprint that locked the 6 V1 modules, learner journey, and instructor workflow before any UI work, with each module documented as a one-page spec that the education team signed off so scope changes were negotiated rather than silently absorbed. Sprint one delivered course catalog and cohort enrollment against stubbed content, while sprint two introduced lesson access, assignment submission, and instructor review, with the enrollment-state machine tests written before the handlers so illegal transitions failed the build immediately. QA covered the full enrollment and progress lifecycle on each build, with particular attention to payment-state and refund edge cases that could erode learner trust, including negative tests that verified a refunded learner lost lesson access within seconds of the webhook firing. Each sprint closed with a demoable release reviewed by the education team, and release sequencing kept instructor dashboards in the same sprint as the learner feature they supported so no learner-facing feature shipped without the instructor visibility to manage it.
A hardening sprint before launch stress-tested payment-state transitions, progress-tracking accuracy, and certificate eligibility logic, since these were the workflows most likely to generate support load, and each was tested against a synthetic cohort of two hundred learners to surface concurrency bugs in the progress recomputation path. Automated regression checks validated that no learner could access lessons outside their enrollment and that progress reconciled against the assignment record, with a nightly job that compared the cached progress counter against a fresh recompute and flagged any drift to the on-call channel. The final release checklist included cloud handoff, monitoring for failed enrollments with alerting wired to the on-call rotation, and a support runbook for refund disputes that walked agents through reading the enrollment ledger and the corresponding Stripe event. This sequencing kept the education MVP focused on the learning loop while leaving a documented backlog for certificates, community, and enterprise licensing, each item annotated with the enrollment-volume trigger that would justify building it.
Operational challenges and resolutions
The dominant operational challenge was course content quality, where inconsistent lesson structure broke learner progress and generated support tickets that consumed instructor time better spent on grading. The resolution was a mandatory course publishing checklist enforced at publish time that required each lesson to have objectives, content, and at least one assessment, plus an admin review queue for courses flagged by automated completeness checks that scanned the Sanity content graph for missing fields. Payment-state ambiguity, where refunds and partial scholarships overlapped on modified enrollments and produced conflicting balance states, was resolved by modeling enrollment as a ledger event stream that mirrored every Stripe event, with a nightly reconciliation job flagging mismatches between the local ledger and the Stripe balance for manual review before any learner noticed. Progress-tracking drift, where completed lessons were not reflected accurately because a cached counter fell out of sync, was handled by recomputing progress from the assignment record rather than trusting a cached counter, and the recompute ran on every progress read with a short TTL cache to avoid hammering the database.
Instructor review backlog was a second challenge, where ungraded assignments piled up and frustrated learners who were blocked on feedback before the next lesson; the team introduced a review queue dashboard with SLA alerts that flagged any assignment ungraded beyond the configured threshold so instructors could prioritize effectively. Cohort scheduling conflicts, where instructors were double-booked across overlapping cohorts, were resolved by conflict-checked scheduling at the database level using a Postgres exclusion constraint on the (instructor_id, cohort_window) range so a double booking was rejected before any learner was enrolled. Each resolution was captured as a runbook so the education operations team could manage the platform independently after handoff, with each runbook linked from the admin console so operators did not have to hunt through a separate documentation site. These operational fixes directly supported the 6 modules scoped for V1, and the publishing checklist became the foundation for the content-quality analytics that informed which course categories warranted additional instructional investment.
Admin and operator tooling
The admin console covered course publishing review, cohort scheduling, instructor management, enrollment dispute resolution, refund authorization, and education reporting, with each surface built as a tab rather than a separate page so operators could switch context without losing their filter state. Operators could view course publishing status, cohort fill rates, and learner progress on a single dashboard, with drill-downs into individual records that preserved the cohort context so an operator investigating a refund always saw the learner enrollment and assignment history together. Support tooling linked each ticket to the underlying enrollment and assignment record, giving agents full context without switching systems, and the ticket view rendered the enrollment ledger inline so agents could see the Stripe event that triggered the dispute without opening a separate payment console. Reporting dashboards exposed enrollment volume, completion rate, refund rate, and instructor review SLA, refreshed on a near-real-time pipeline backed by a materialized view that recomputed every five minutes so the numbers were never more than a few minutes stale.
Operational controls included configurable refund policies with per-cohort windows, a learner block list for abuse that prevented new enrollments while letting active ones complete, a course takedown workflow for quality issues that revoked access and notified affected learners, and a release-control surface for toggling features per cohort so a new capability could be piloted with one cohort before a platform-wide rollout. The admin dashboard provided audit logs for every refund authorization and publishing change so post-incident reviews had a clear trail, and the logs were filterable by instructor, cohort, and time window so a dispute could be reconstructed in minutes. This tooling layer was what made the education platform operable at launch, not just enrollable, and it directly enabled the 6 modules scoped for V1. Instructional teams could publish courses and manage cohorts without engineering involvement, keeping the learning cadence independent of the deploy cycle, which mattered because course launches were time-sensitive and a delayed deploy could mean a cohort starting without its content live.
Launch outcomes and lessons
The MVP launched with a curated set of cohorts and a documented expansion playbook, proving the learning loop before any community or enterprise licensing modules were added, and the curated launch kept the support surface area small enough that the education team could personally respond to every learner ticket during the first cohort. What worked well was the cohort-scoped progress model, which kept learner data clean across cohorts and prevented the cross-cohort contamination that plagues generic LMS deployments, and the course publishing checklist, which reduced content-quality support tickets at launch by catching missing assessments before learners ever saw the lesson. What did not work was underestimating instructor review backlog, which required the SLA dashboard after the first cohort when ungraded assignments piled up and learners started emailing the education team directly. The lesson was that instructor tooling must ship with the learner feature, not after it, because a learning product without responsive feedback is just a content library and learners will churn. A third lesson, surfaced after the second cohort launched, was that the course publishing checklist needed a per-lesson preview mode so instructional teams could review a lesson exactly as a learner would see it before publishing, because several courses shipped with broken content links that the completeness check could not detect since the links existed but pointed to the wrong Sanity document.
A second lesson was that enrollment should be modeled as a ledger event stream from day one, since a single payment flag would have collapsed under refunds and scholarships and the team would have had to reconstruct financial history from Stripe exports after the fact. Founders evaluating a similar cohort learning build should resist launching community or enterprise licensing early, because their operational complexity dwarfs the learning MVP and community moderation alone can consume a full-time hire before any revenue justifies it. The anonymized launch plan captured these lessons as a checklist for the next course rollout, with each item tied to the specific incident or near-miss that produced it so the next team understood the reasoning rather than just the rule. Overall, the launch validated that clone-inspired education products succeed when the operating layer is engineered as carefully as the learner experience, and that the unglamorous parts—ledger events, publishing checklists, and SLA dashboards—are what keep a cohort platform credible once learners start paying for outcomes.
Scalability and post-launch evolution
The architecture was designed to scale by keeping transactional data in PostgreSQL with cohort-scoped progress tracking, with Sanity handling content at scale without coupling to the transactional store so a content publish never triggered a database migration. The Node.js service layer was deployed with autoscaling on AWS behind an application load balancer, and the assignment-status event channel was built to fan out across instances using a shared Redis pub-sub layer so a learner on one instance and an instructor on another saw the same status update within seconds. The enrollment ledger was designed to partition by cohort so reconciliation jobs could run in parallel as the course catalog grew, with each partition scanned independently so a reconciliation run on a large cohort did not block a small one. Deferred to later phases were community features, enterprise licensing, advanced analytics, and a certificate verification service, each scoped as a separate module to avoid entangling the learning loop and each given an interface contract so the core could call them without knowing their internals.
Post-launch evolution followed the documented backlog: new courses were published through the checklist with cohort scheduling reconfigured without deploys, validated through per-cohort feature toggles so a misconfigured course could be paused without affecting the rest of the catalog. Reporting was upgraded from near-real-time to a streaming pipeline once enrollment volume justified the investment, with the materialized views replaced by a Kafka-backed stream that fed a ClickHouse warehouse so the education team could run completion-cohort analysis across months of enrollments without loading the transactional database. The progress-tracking service later absorbed a certificate verification module that issued tamper-evident certificates with a public verification endpoint, but only after the MVP proved that deterministic eligibility was sufficient for launch and after enough completions existed to justify the verification infrastructure. This phased evolution kept the education platform stable under growth while preserving the original clone-inspired speed of the first release, and the discipline of deferring each module until its predecessor was proven meant the team never carried more than one major capability in flight at a time.
Related case records