Editorial dossier / Logistics
Courier Dispatch Dashboard Requirements: Assignment, Tracking and Exceptions
Design courier dispatch dashboards around shipment states, driver capacity, assignments, tracking freshness, SLA risk, proof, exceptions and recovery.
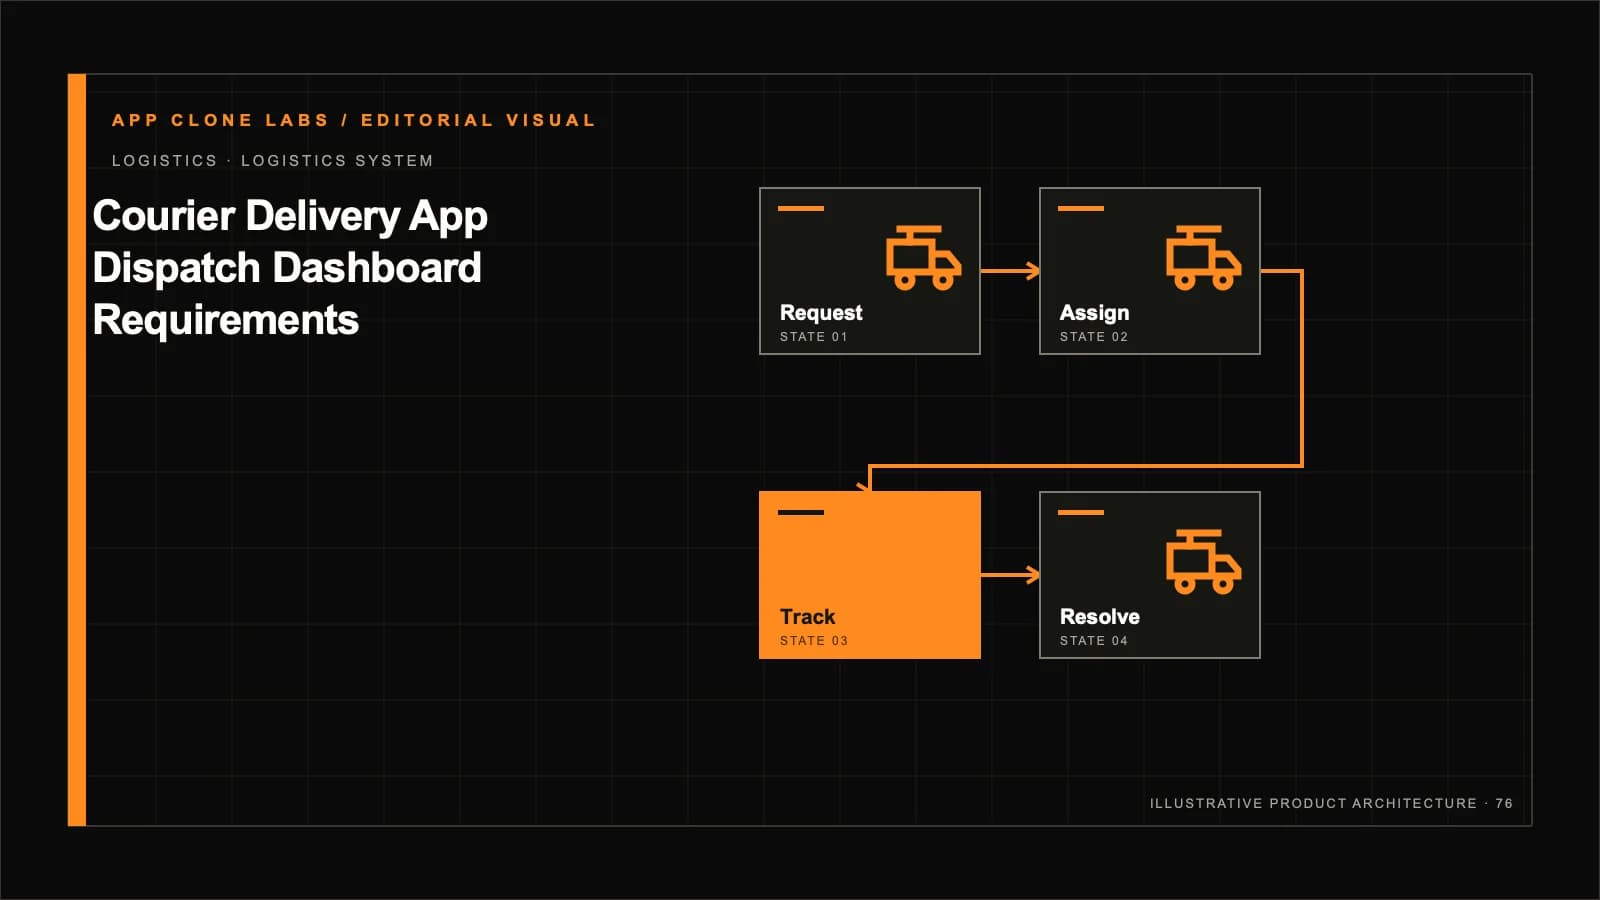
A dispatch dashboard should not make operators admire moving markers. It should tell them which delivery promise is at risk, why the current assignment is failing and which bounded action will improve the outcome.
Location is only one signal. Capacity, shipment state, evidence freshness, driver authority and customer communication determine whether the operation is actually under control.
This guide designs the control tower around decisions and exceptions.
Define shipment obligations
Define shipment obligations is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements define shipment obligations as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for define shipment obligations before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For define shipment obligations, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For define shipment obligations, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned define shipment obligations decision record and acceptance results
- Stop condition: define shipment obligations cannot be explained, bounded or recovered from durable evidence
Model stops and routes
Model stops and routes is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements model stops and routes as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for model stops and routes before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For model stops and routes, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For model stops and routes, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned model stops and routes decision record and acceptance results
- Stop condition: model stops and routes cannot be explained, bounded or recovered from durable evidence
Represent driver eligibility
Represent driver eligibility is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements represent driver eligibility as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for represent driver eligibility before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For represent driver eligibility, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For represent driver eligibility, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned represent driver eligibility decision record and acceptance results
- Stop condition: represent driver eligibility cannot be explained, bounded or recovered from durable evidence
Show current capacity
Show current capacity is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements show current capacity as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for show current capacity before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For show current capacity, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For show current capacity, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned show current capacity decision record and acceptance results
- Stop condition: show current capacity cannot be explained, bounded or recovered from durable evidence
Checkpoint 4: reconcile the product promise with the recorded state. Support, finance, security, and delivery teams should be able to reach the same conclusion from the same identifiers without reconstructing events from chat messages or screenshots.
Reserve and confirm assignments
Reserve and confirm assignments is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements reserve and confirm assignments as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for reserve and confirm assignments before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For reserve and confirm assignments, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For reserve and confirm assignments, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned reserve and confirm assignments decision record and acceptance results
- Stop condition: reserve and confirm assignments cannot be explained, bounded or recovered from durable evidence
Expose tracking freshness
Expose tracking freshness is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements expose tracking freshness as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for expose tracking freshness before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For expose tracking freshness, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For expose tracking freshness, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned expose tracking freshness decision record and acceptance results
- Stop condition: expose tracking freshness cannot be explained, bounded or recovered from durable evidence
Calculate ETA uncertainty
Calculate ETA uncertainty is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements calculate eta uncertainty as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for calculate eta uncertainty before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For calculate eta uncertainty, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For calculate eta uncertainty, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned calculate eta uncertainty decision record and acceptance results
- Stop condition: calculate eta uncertainty cannot be explained, bounded or recovered from durable evidence
Prioritize SLA risk
Prioritize SLA risk is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements prioritize sla risk as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for prioritize sla risk before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For prioritize sla risk, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For prioritize sla risk, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned prioritize sla risk decision record and acceptance results
- Stop condition: prioritize sla risk cannot be explained, bounded or recovered from durable evidence
Checkpoint 8: reconcile the product promise with the recorded state. Support, finance, security, and delivery teams should be able to reach the same conclusion from the same identifiers without reconstructing events from chat messages or screenshots.
Create exception queues
Create exception queues is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements create exception queues as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for create exception queues before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For create exception queues, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For create exception queues, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned create exception queues decision record and acceptance results
- Stop condition: create exception queues cannot be explained, bounded or recovered from durable evidence
Support manual reassignment
Support manual reassignment is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements support manual reassignment as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for support manual reassignment before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For support manual reassignment, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For support manual reassignment, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned support manual reassignment decision record and acceptance results
- Stop condition: support manual reassignment cannot be explained, bounded or recovered from durable evidence
Protect driver safety actions
Protect driver safety actions is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements protect driver safety actions as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for protect driver safety actions before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For protect driver safety actions, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For protect driver safety actions, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned protect driver safety actions decision record and acceptance results
- Stop condition: protect driver safety actions cannot be explained, bounded or recovered from durable evidence
Capture proof status
Capture proof status is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements capture proof status as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for capture proof status before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For capture proof status, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For capture proof status, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned capture proof status decision record and acceptance results
- Stop condition: capture proof status cannot be explained, bounded or recovered from durable evidence
Checkpoint 12: reconcile the product promise with the recorded state. Support, finance, security, and delivery teams should be able to reach the same conclusion from the same identifiers without reconstructing events from chat messages or screenshots.
Coordinate customer communication
Coordinate customer communication is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements coordinate customer communication as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for coordinate customer communication before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For coordinate customer communication, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For coordinate customer communication, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned coordinate customer communication decision record and acceptance results
- Stop condition: coordinate customer communication cannot be explained, bounded or recovered from durable evidence
Audit dispatcher actions
Audit dispatcher actions is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements audit dispatcher actions as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for audit dispatcher actions before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For audit dispatcher actions, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For audit dispatcher actions, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned audit dispatcher actions decision record and acceptance results
- Stop condition: audit dispatcher actions cannot be explained, bounded or recovered from durable evidence
Operate regional incidents
Operate regional incidents is an independent operating decision inside a courier operation coordinating shipments, drivers, capacity and customer promises. It affects the public promise, the authority of each participant, the evidence retained by the platform and the recovery path when ordinary processing fails.
The failure mode is concrete: the team implements operate regional incidents as a screen-level feature, leaving permissions, downstream state, financial effects and support behavior inconsistent. This is not solved by adding another screen or background job. The product has to define ownership, permitted transitions, and the evidence retained when the transition occurs.
For the first release, write the authoritative lifecycle, responsible role, permitted transitions and user-visible outcome for operate regional incidents before adding interface breadth. Write that decision as an enforceable server-side rule, not guidance that depends on a client, operator, or AI model remembering the intended boundary.
Implementation should include For operate regional incidents, retain stable identifiers, explicit states, server-side authorization, version checks, occurrence and processing times, reason codes, correlation identifiers, audit history and an owned exception route. Keep the public response smaller than the internal record: users need a clear outcome and recovery path, while authorized operators need correlation IDs, policy versions, timestamps, and the before-and-after state.
Validate it with For operate regional incidents, run the successful journey followed by duplicate delivery, stale state, concurrent commands, revoked authority, dependency timeout, partial failure, operator correction and later reconciliation. Test the ordinary path, then repeat under timeout, duplicate delivery, stale state, partial failure, revoked authority, and concurrent requests. A feature is not ready when only the demonstration succeeds.
- Owner: product owner
- Release evidence: versioned operate regional incidents decision record and acceptance results
- Stop condition: operate regional incidents cannot be explained, bounded or recovered from durable evidence
Implementation references
Use GS1 transport and logistics standards and record the version used for release.
Validate against W3C Geolocation API and record the version used for release.
Review IETF GeoJSON RFC 7946 and record the version used for release.
Compare with OWASP API Security Top 10 and record the version used for release.
Continue with Courier Delivery Blueprint when converting this guide into scope.
Frequently asked questions
What should dispatch show first?
Unassigned work, SLA risk, stale tracking and owned exceptions.
Is a live map enough?
No. Operators need state, capacity, evidence and action context.
How is double assignment prevented?
Reservation, version checks and idempotent acceptance.
How should stale GPS appear?
Explicitly as stale, with captured time and accuracy.
What actions need audit?
Assignment, cancellation, status override, proof correction and customer-impacting changes.
How should exceptions work?
Typed cases with evidence, owner, next action and deadline.
What happens during a map outage?
Use degraded lists, last-known evidence and recovery reconciliation.
What should be tested?
Concurrency, offline drivers, stale location, reassignment, proof failure and regional outage.
Turn the plan into release evidence
A credible release connects its promise to durable state, scoped authority and recoverable operations. The team should explain ordinary journeys and important exceptions from the same evidence.
Keep the first scope narrow enough to rehearse. Expand only after permissions, data, money and support outcomes remain consistent under retries, failures and human mistakes.
- 01
- 02
- 03
- 04
- 05
- 06
Reviewed by the App Clone Labs product strategy team
This guide is written for founders and operators planning clone-inspired platforms, SaaS products, marketplaces, and mobile apps. It is reviewed against App Clone Labs delivery patterns, product scoping standards, and current implementation realities before being published.
Review the editorial team structureRelated product paths
Continue with the services, solutions, guides, and articles that connect this topic to a real software build.
Services, solutions, and guides
Read next